“If your only tool is a hammer, every problem looks like a nail.”
Often attributed to Abraham Maslow, The Psychology of Science (1966).
Well, at least I’ve got a hammer and a screwdriver: deterministic structural checks and IA. Let’s try to see how this could apply to content engineering.
The first is deterministic. The second relies on probabilistic inference. If we don’t try to hammer a nail with a screwdriver or turn a screw with a hammer, we might find interesting ways to improve CI/CD pipelines for content creation.
This article explores how such a pipeline might work, what it could detect, and how to test whether it is useful in practice.
A five-stage validation pipeline: 1. Conventional Markdown (author-written documentation), 2. AI semantic analysis (infer purpose and propose a candidate structure as an unverified interpretation), 3. Candidate structure (explicit elements and relationships as an inspectable intermediate artifact). Across the trust boundary: 4. Deterministic validation (check the structure against purpose-specific rules), 5. CI validation report (pass, fail, or flag for review).
In this theoretical pipeline, responsibilities are cleanly divided across trust boundaries:
A quadrant diagram mapping the three pipeline responsibilities across two conceptual axes. Horizontal axis: Formal verification (left) to Semantic interpretation (right). Vertical axis: Automated (bottom) to Human-led (top). 1. Deterministic code (Automated / Formal verification): Automated structural checks validate structural rules (such as every step being reachable, no circular dependencies, and complete branches) against explicit purpose contracts. Proves candidate structure, not prose meaning. 2. AI semantic analysis (Automated / Semantic interpretation): An LLM infers the document's intended reader purpose and extracts a candidate structure of relationships from ordinary Markdown prose. Proposes an unverified candidate model, not established factual proof. 3. Human review (Human-led / Semantic interpretation): An editorial workflow reviews ambiguous classifications, low-confidence extractions, or edge cases flagged as inconclusive. This review is conditional and not required for every document. 4. Unoccupied (Human-led / Formal verification): Formal verification in this pipeline is handled entirely by automated deterministic code; there is no manual verification role.
Example: troubleshooting guide
Let’s consider the following troubleshooting guide:
# E247: System fault detected

The system has detected an operational problem.

## Condition

An indicator signals a fault, and the system log contains a corresponding error message.

## Cause

A temporary fault has occurred.

## Remedy

**Responsible party:** System administrator

1. Open the system management interface.
2. Locate the reported fault.
3. Acknowledge or reset the fault.
4. Monitor the system for recurring faults.
5. Review the system log to verify that the fault has cleared.
What conventional linters see
For a Markdown parser, a document is a tree, similar to an HTML Document Object Model. Linters check heading levels and list numbering syntax. Link checkers check hyperlinks.
But how can we know whether the guide actually helps users troubleshoot the issue at hand?
A linter cannot tell how long step 4 lasts, what the user should do if the fault recurs, or what happens if step 5 shows that the fault has not cleared. To the parser, the five remedy steps are simply five sequential strings.
To bridge this gap, an automated validation system must distinguish three distinct layers:
- Document structure
- The syntactic elements (headings, ordered lists, code fences, tables) declared in Markdown syntax.
- Semantic structure
- Transitions described by the prose.
- Purpose
- User’s goal.
Extract candidate semantic relationships
Where a tree parser sees only list syntax, a language model can interpret natural language cues to infer the underlying semantic structure:
- Document type
- Troubleshooting guide.
- Step extraction
- Actions, checks, and outcomes.
- Transition extraction
- Sequential transitions (step order) and the outcomes that checks imply (e.g., verify that the fault has cleared).
You thus get a structure of relationships, not an established factual proof.
Mapping the model
First, map text chunks and transitions into an explicit model. Then, you can programmatically check the relationships between the Markdown constructs:
A candidate remedy flow showing five steps. Step 1 (Open management interface) leads to Step 2 (Locate fault), then Step 3 (Reset fault), then Step 4 (Monitor system), then Step 5 (Review system log). Step 5 leads to an implied outcome, Fault cleared, if the fault has cleared. Step 4 has no next step if the fault recurs, and Step 5 has no next step if the fault persists.
Check rules
You can then programmatically evaluate the structure against explicit rules:
- Contract rule
- Every check must lead to a next step, a retry loop, or an outcome for each of its possible results.
- Rule evaluation
- Structural checks count the transitions after each check:
- Step 4 (“Monitor the system for recurring faults”) has no exit condition. The text never says how long to monitor or what to do if the fault recurs.
- Step 5 (“Review the system log to verify that the fault has cleared”) covers only one result. If the fault has not cleared, users are stranded without remediation or escalation steps.
- Pipeline outcome
- The validator flags this document as
nok, citing the specific Markdown line numbers where checks lack downstream transitions.
In an authoring environment, this diagnostic feedback alerts the writer to an omission that syntax linters ignore.
If the author gives step 4 a monitoring period and adds an escalation path to step 5 (for example, “If the fault persists, contact service”), every path ends in a resolution or an escalation.
Limitation: structural checks versus prose accuracy
Suppose the author updates the Markdown so that all branches lead to valid destinations, and the validator reports that the extracted structure satisfies every structural rule:
Every step can be reached, every action leads to a next check, an intentional retry, or a terminal state, and no unhandled dead ends exist.
This deterministic structural check does not prove that the documentation is accurate or clear.
Structural checks can confirm the properties of the candidate data structure, but they cannot verify whether the AI model interpreted the author’s prose correctly.
The model might have hallucinated a step, inverted a condition, or overlooked a technical subtlety. Structural validation provides machine-verifiable safety rails over an inspectable, evidence-backed model, not a proof of linguistic correctness.
Can documentation be modeled as a structure of relationships?
Documentation describes relationships between its elements. A step leads to the next step, a check sends the user down one of two paths, a concept depends on another concept, and a page links to related pages.
To check those relationships automatically, a system records each element (such as a step, check, concept, or page) and each relationship that points from one element to another (such as a transition, dependency, prerequisite, or conceptual association).
To apply this kind of modeling to documentation, an automated system must decide what structure to expect from a given Markdown file.
Why not map structure directly to Markdown syntax?
A naive approach would assign a structure directly to common Markdown formatting patterns:
- An ordered list becomes a linear sequence.
- A nested bullet list becomes a branching tree.
- Heading levels form a conceptual taxonomy.
In practice, syntax mapping quickly breaks down:
- A numbered list is not necessarily a sequence of dependent steps; authors frequently use numbered lists for prioritized tips, independent options, or arbitrary feature lists where order does not imply sequence.
- A nested list is not inherently a branching workflow; it often represents grouped examples or taxonomic bullet points.
- A hierarchy of headings rarely forms a strict conceptual tree; subheadings often introduce parallel perspectives or procedural steps rather than parent-child relationships.
Markdown syntax provides surface clues about layout and typography, but the semantic meaning of that structure depends entirely on the prose.
A viable validator cannot rely on syntax mapping alone. It requires two distinct stages: first inferring what the document is attempting to accomplish, and then deterministically testing whether its extracted relationships satisfy the constraints expected for that purpose.
Grounding validation in user purposes
If an AI model were allowed to invent an ad hoc category for every document it analyzes, validation rules would quickly become unpredictable. An open-ended taxonomy gives the model too much freedom to rationalize idiosyncratic structural choices.
To keep automated verification predictable, the system constrains the model to a small, provisional taxonomy of user purposes, focusing on intended user outcomes rather than file formats or markup conventions:
- User purposes
- Describe what the user wants to achieve (such as accomplishing a task, acquiring a skill, or recovering from an error).
- Candidate structures
- Describe the entities and relationships required by that purpose, and how they are arranged (such as a linear sequence of steps, prerequisites without circular dependencies, or a diagnostic flow with intentional retry loops).
- Document type contracts
- Specify the structural rules (such as every step being reachable, no circular dependencies, or complete required attributes) that deterministic code tests against the extracted structure.
Focusing on user outcomes rather than file titles or syntax avoids brittle assumptions:
- Two documents with different titles can serve the same purpose.
- Two documents with similar titles can require completely different structural checks. For example, a page titled “Getting started” might be a tutorial if it teaches a core skill through guided, interdependent exercises; or it might be an orientation page if it serves as a portal directing users to external installation guides, configuration references, and troubleshooting guides.
Seven purposes and eight candidate structures
The taxonomy distinguishes seven user purposes but explores eight candidate structures. This distinction arises because procedural content divides naturally into two distinct execution structures:
- Linear execution flows (such as standard sequential installation steps), modeled as an unbranching linear sequence.
- Conditional branching workflows (such as platform-specific deployments), modeled as a branching workflow.
This mapping is exploratory, not an absolute one-to-one mandate:
- Not a strict one-to-one mapping
- Real-world documentation does not always fit neatly into a single category. An article might legitimately explain a conceptual architecture before presenting a step-by-step procedure.
- Handling mixed purposes
- An experimental validator must explore whether an LLM can isolate distinct functional sections or identify the dominant document type contract, reporting ambiguity or evaluating sections independently rather than forcing an artificial single-label classification.
- Prose nuance
- A validator can verify that an extracted structure satisfies a document type contract’s structural rules, but it cannot prove that the model correctly interpreted the author’s prose.
Comparing purposes, models, and validation contracts
Table 1 maps the seven user purposes to their candidate structures, primary goals, and potential validation focuses:
| User purpose | What the user wants to achieve | Candidate structure | Potential validation focus |
|---|---|---|---|
| Procedure | Accomplish a concrete task through an actionable sequence of steps. | Linear sequence of steps or branching workflow (conditional) | Terminal goal can be reached; single start state; all conditional branches converge on valid destinations without dead ends. |
| Tutorial | Acquire a new skill or mental model through a progressive, guided learning track. | Dependency structure without circular dependencies | Prerequisite ordering; no circular dependencies (ensuring no concept depends on an activity that itself requires that concept). |
| Explanation | Understand domain architecture, design rationale, and conceptual relationships. | Concept map (entities linked by labeled relationships) | Referential integrity; declared relationships cite textual evidence; reciprocal feedback loops permitted. |
| Reference | Retrieve precise technical specifications, configurations, or API parameters. | Entities with structured key-value attributes | Schema conformity; presence of mandatory attributes (such as auth and payload types); identifier resolution. |
| Troubleshooting | Diagnose, isolate, and recover from a fault or unexpected failure state. | Diagnostic flow with intentional retry loops | Diagnostic checks branch on both failure and success; retry loops contain exit criteria; paths resolve to recovery or escalation. |
| Orientation | Discover resources, explore an information space, and navigate to the relevant documentation section. | Navigation map with lateral cross-links | Every page reachable from the entry point; absence of orphaned pages; bidirectional cross-referencing between related task guides. |
| Change record | Understand what changed across software versions and evaluate component-level migration impact. | Chronological release sequence with component-impact links | Strict chronological order along the release sequence; impact links resolve to verified component entries in an architectural catalog. |
Exploring candidate documentation structures
Users do not need to memorize all eight candidate models to follow the pipeline architecture.
The following four content families illustrate how different user outcomes translate into explicit structures, why validation rules must vary by purpose, and how real-world systems exhibit comparable structures.
For each structure, the candidate model answers three fundamental questions:
- What does the structure represent?
- What property might a validator check?
- What limitation or exception matters?
Linear sequences and branching workflows
Procedures guide users through a series of steps to perform a task. An automated validator tests whether those actions form viable, unbroken execution paths from start to completion.
Structure: Linear sequence of steps. Semantic purpose: sequential procedure. A sequence of four rectangular boxes connected from top to bottom by arrows: Prepare, Install CLI, Authenticate, and Service running.
-
A strictly sequential procedure where each action between the first and the last has exactly one predecessor and one successor, guiding the user along an unbranching path toward a single terminal goal.
-
A validator checks a single entry point, unbroken path reachability from the start to the terminal state, and no unhandled dead ends or unexpected branches.
-
A numbered Markdown list is not equivalent to a linear sequence of dependent steps. Authors often use numbered lists for non-sequential tips, independent options, or arbitrary feature lists where order does not imply sequence.
Furthermore, real-world procedures often contain optional steps or recovery branches that break pure linearity.
Physical analogy: Automotive assembly line
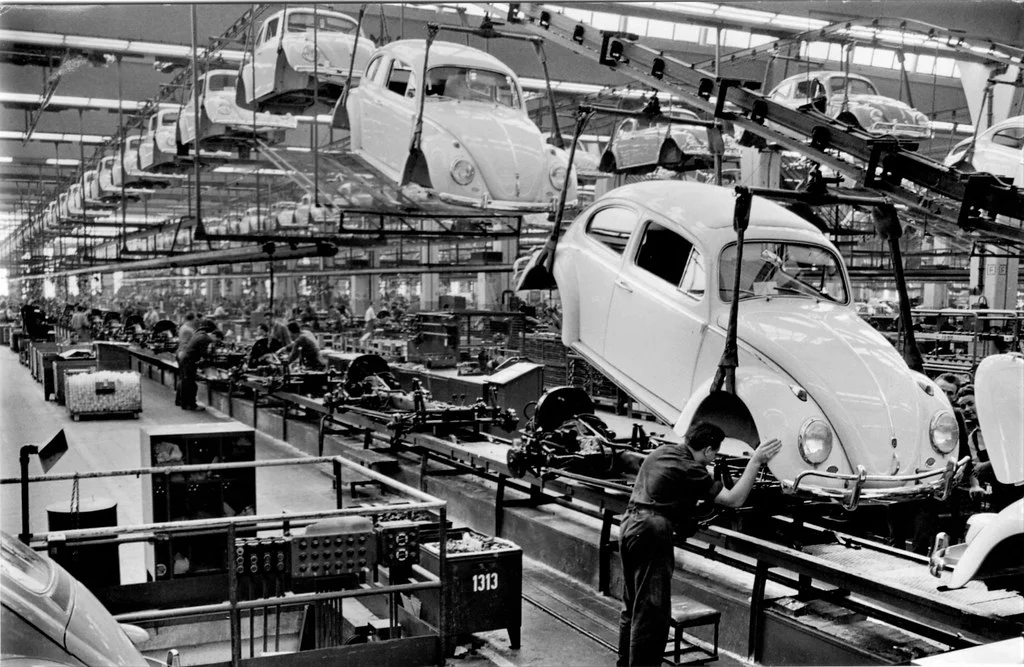
An automotive assembly line moving sequentially through progressive production stages illustrates an unbranching execution path. Photo: “Volkswagen Beetle Assembly Line” by aldenjewell, licensed under CC BY 2.0.
Structure: Branching workflow. Semantic purpose: conditional procedure. A branching workflow starting at Select target, branching into Cloud setup and On-prem setup tracks, then converging on Production ready.
-
A conditional procedure containing explicit decision points (such as selecting a cloud provider or on-premises environment) that diverge into separate execution tracks before converging on a verified terminal state.
-
A validator checks decision completeness: every declared decision branch must lead to an actionable subsequent step, and all diverging tracks must eventually converge on a valid terminal outcome rather than terminating in an orphaned dead end.
-
A branching workflow models mutually exclusive conditional paths, not parallel concurrent execution or simple linear steps. Text linters cannot verify whether all platform options are covered or whether conflicting branch prerequisites are handled.
Physical analogy: Branching road junction
Aerial view of a branching road junction and traffic intersection, illustrating conditional routing diverging across distinct paths. Photo: “Intersection, road, junction” via PxHere, licensed under CC0.
Concepts
Concept topics equip users with skills and domain models.
Structure: Dependency structure without circular dependencies. Semantic purpose: tutorial curriculum. A prerequisite structure starting at Core syntax, branching into Data modeling and API configuration tracks, both required by Pipeline assembly, leading to Certified build.
-
Tutorial curricula and skill prerequisite chains. Learning tracks often branch into parallel foundational topics (such as syntax and data modeling) before converging on an integrated project build.
-
A validator checks for no circular dependencies and an order in which every prerequisite comes before the topics that need it. A validator detects circular dependencies, such as Topic A requiring Topic B while Topic B requires Topic A, which create pedagogical deadlocks for learners.
-
This structure is appropriate only where the learning contract strictly prohibits circular dependencies. It models formal prerequisite constraints, not the exploratory reading sequence of a user who skips ahead or reviews earlier sections.
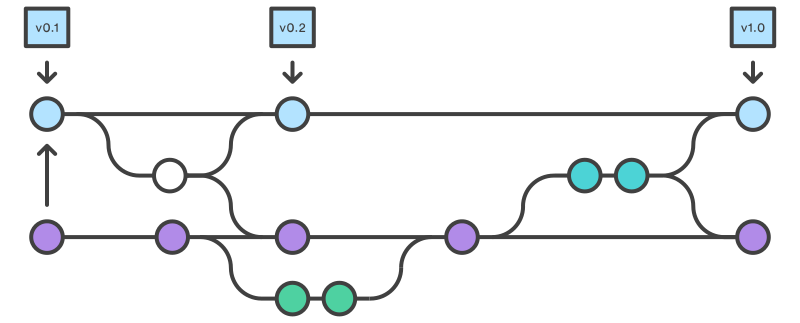
Software analogy: Git branching model (Gitflow)
Structure: Concept map with labeled relationships. Semantic purpose: explanatory domain model. Four concepts: Docs-as-Code, Information architecture, Semantic validator, and Reader persona, connected by labeled relationships including a feedback loop.
-
An explanatory domain model connecting abstract concepts, architectural components, and user personas through labeled, directed relationships.
-
A validator checks connections between concepts, relationship validity, and referential integrity (checking that every cited concept is grounded in the text).
-
Unlike procedural workflows or tutorial curricula, conceptual explanations legitimately exhibit reciprocal relationships and feedback loops (for example, user feedback iteratively evaluating documentation design). Enforcing a no-loops rule here would produce a false positive, and a fully connected set of concepts does not prove explanatory clarity.
Physical analogy: Concept network installation at Futurium
Exhibition installation at Futurium demonstrating interconnected concepts. Photo: “Knowledge graph installation in Futurium” by Daniel Mietchen, licensed under CC0.

Reference and troubleshooting
Reference specifications and troubleshooting guides require specialized structures to handle rich metadata attributes and operational retry loops.
Structure: Entities with structured attributes. Semantic purpose: reference documentation. Three reference entities with embedded attributes: POST endpoint, ValidationSchema, and DecisionReport, connected by labeled arrows that carry their own attributes.
-
Reference specifications (such as REST API endpoints, configuration schemas, or CLI flags) where entities and relationships carry typed key-value metadata attributes directly.
-
A validator checks schema conformity, required attribute completeness (such as verifying that every endpoint specifies authentication requirements and response payload schemas), and identifier cross-referencing.
-
This structure prioritizes structured entity metadata over execution flow. A validator can confirm that all schema fields and types are present, but it cannot determine whether the narrative parameter descriptions are clear, accurate, or complete.
Physical analogy: Delhi Metro transit rail network
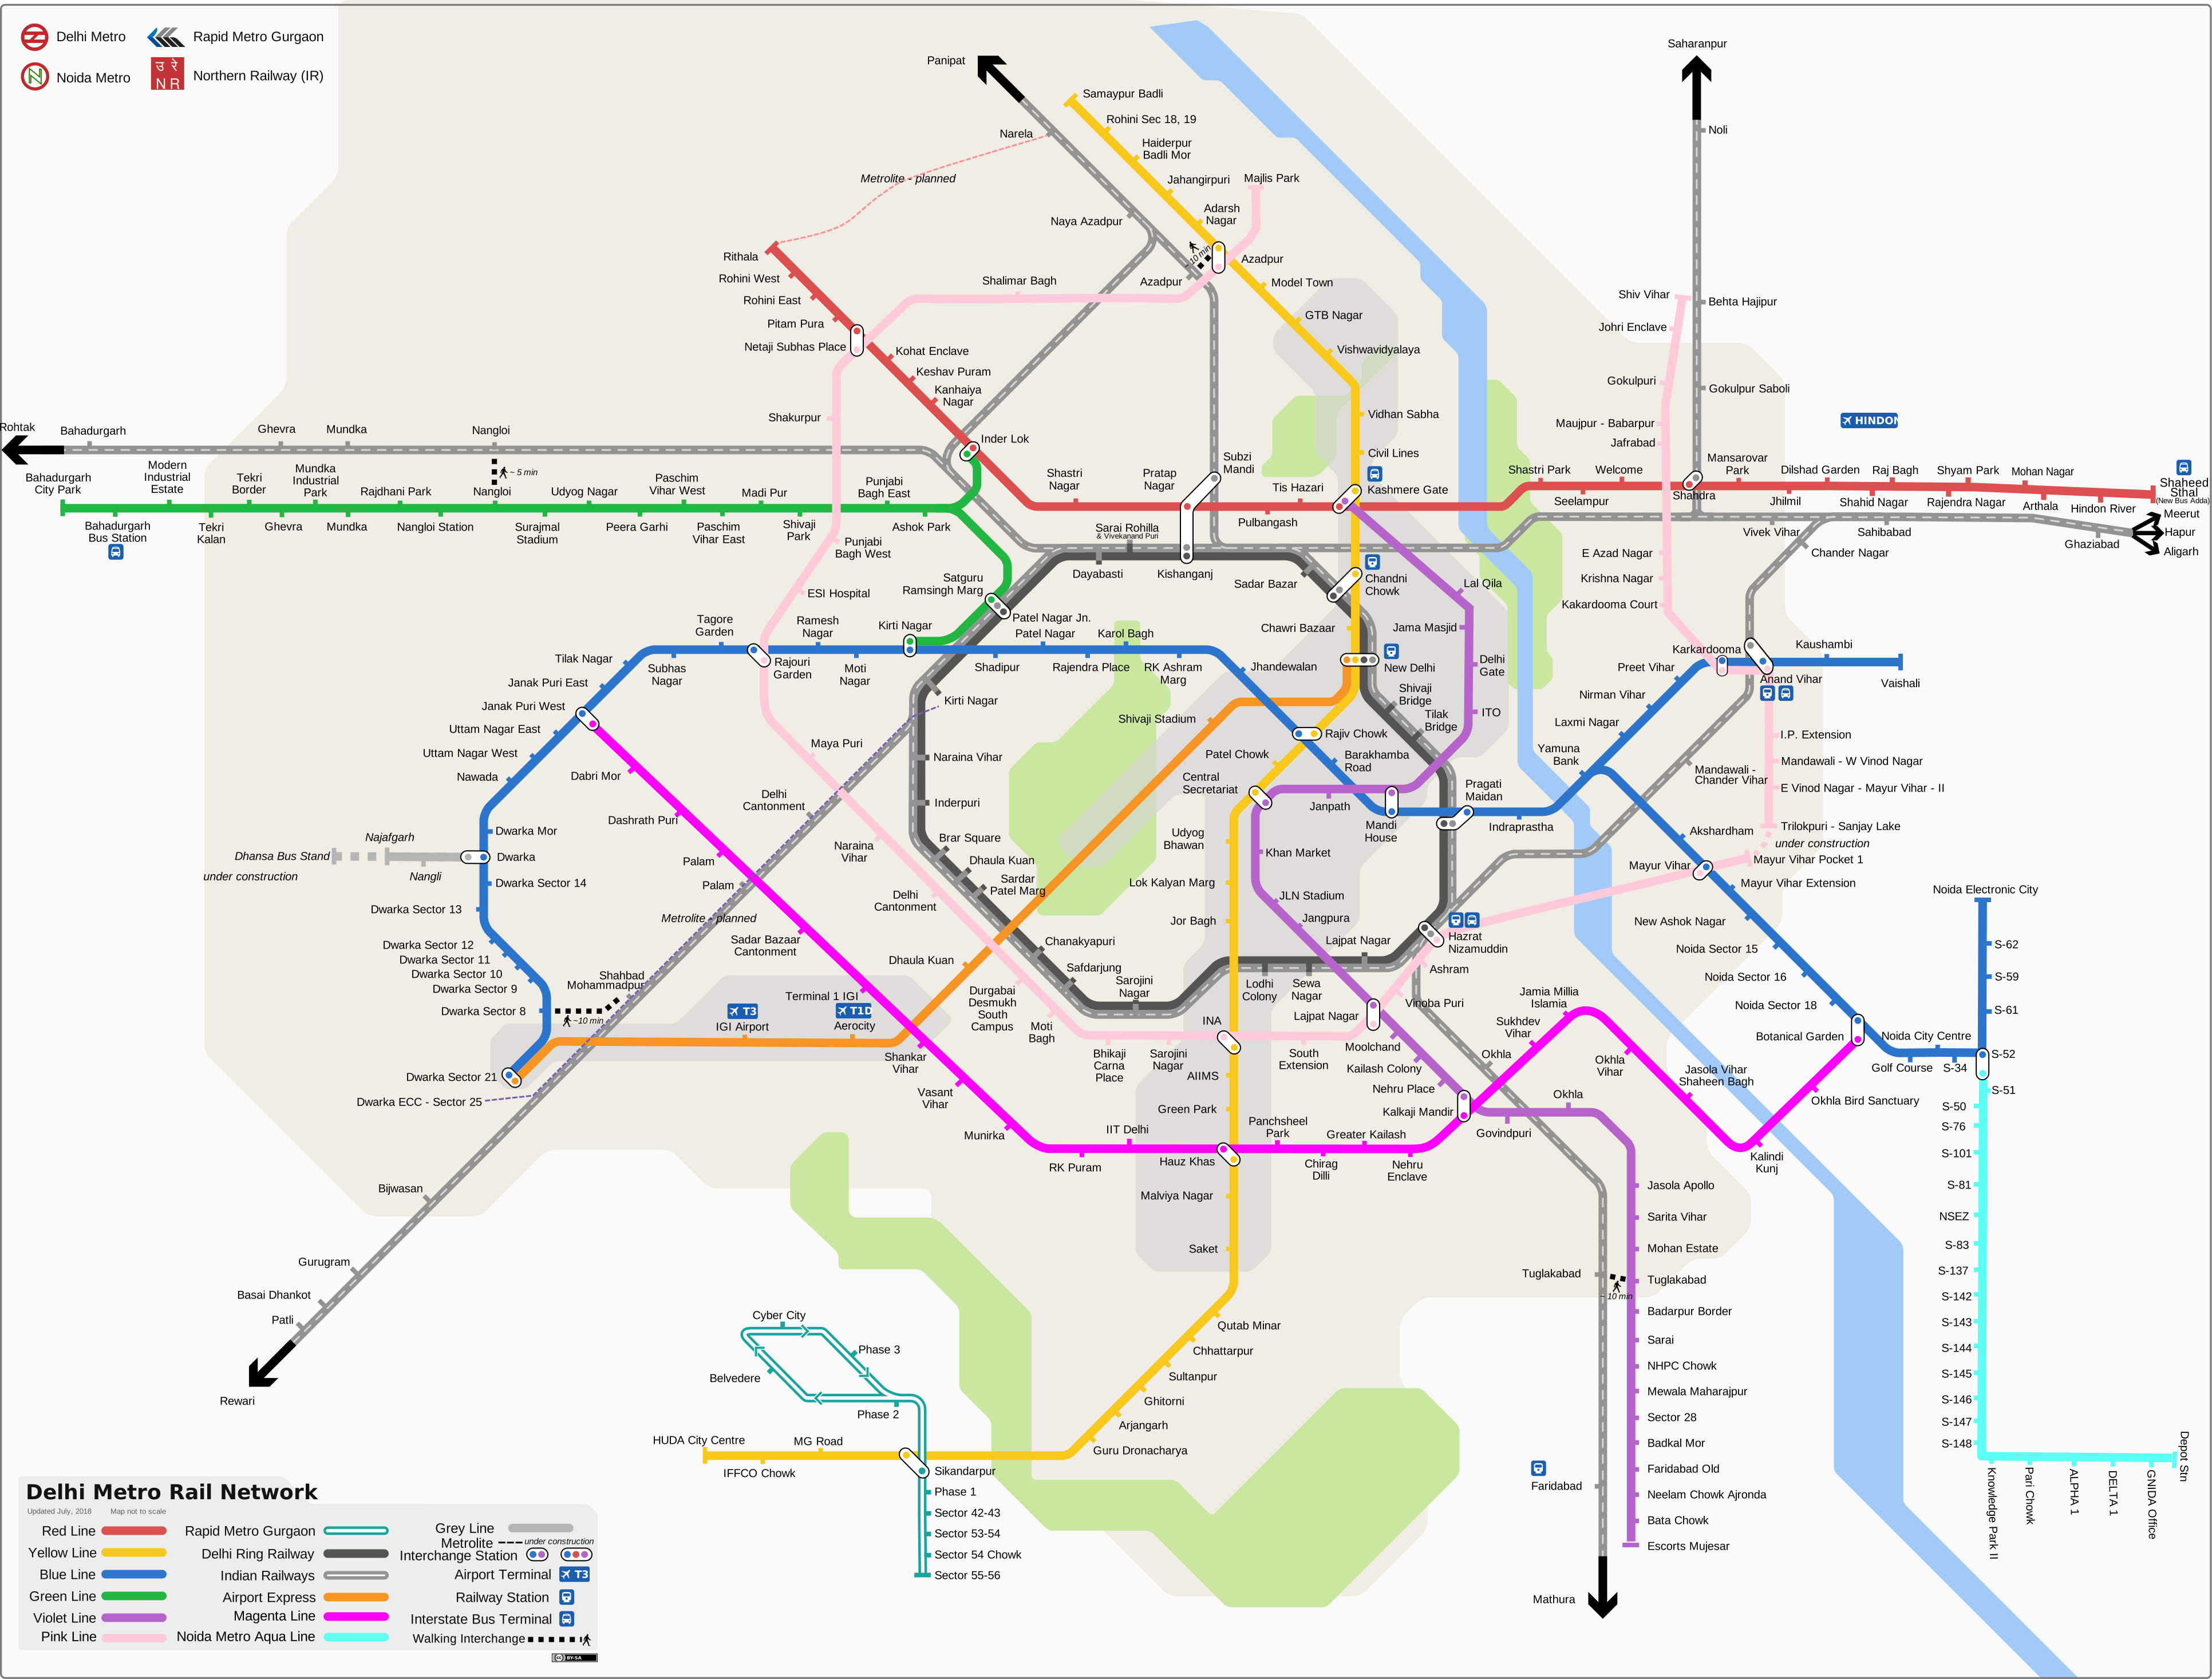
Delhi Metro transit rail network map, where stations and route segments carry structured attributes such as line colors, transfer interchanges, and station identifiers. Map: “Delhi metro rail network” by PlaneMad, licensed under CC BY-SA 2.5.

Structure: Diagnostic flow with an intentional retry loop. Semantic purpose: troubleshooting procedure. A troubleshooting flow starting at Check link status, branching on failure to Restart interface which loops back to Check link status, and branching on success to Test DNS resolution which leads to Service restored or Escalate.
-
A troubleshooting workflow combines tests, corrective actions, and recovery loops that lead to resolution or escalation.
-
A validator checks branch completeness (ensuring checks branch on both success and failure), retry loop exit conditions, and terminal resolution (ensuring no action leaves the user stranded without remediation or escalation).
-
Actual troubleshooting guides do contain retry loops: users must often try a step and re-evaluate the outcome.
A validator checks that users won’t be trapped in a loop forever. It can’t prove they will eventually achieve their tasks.
Clinical analogy: Medical differential diagnosis flowchart
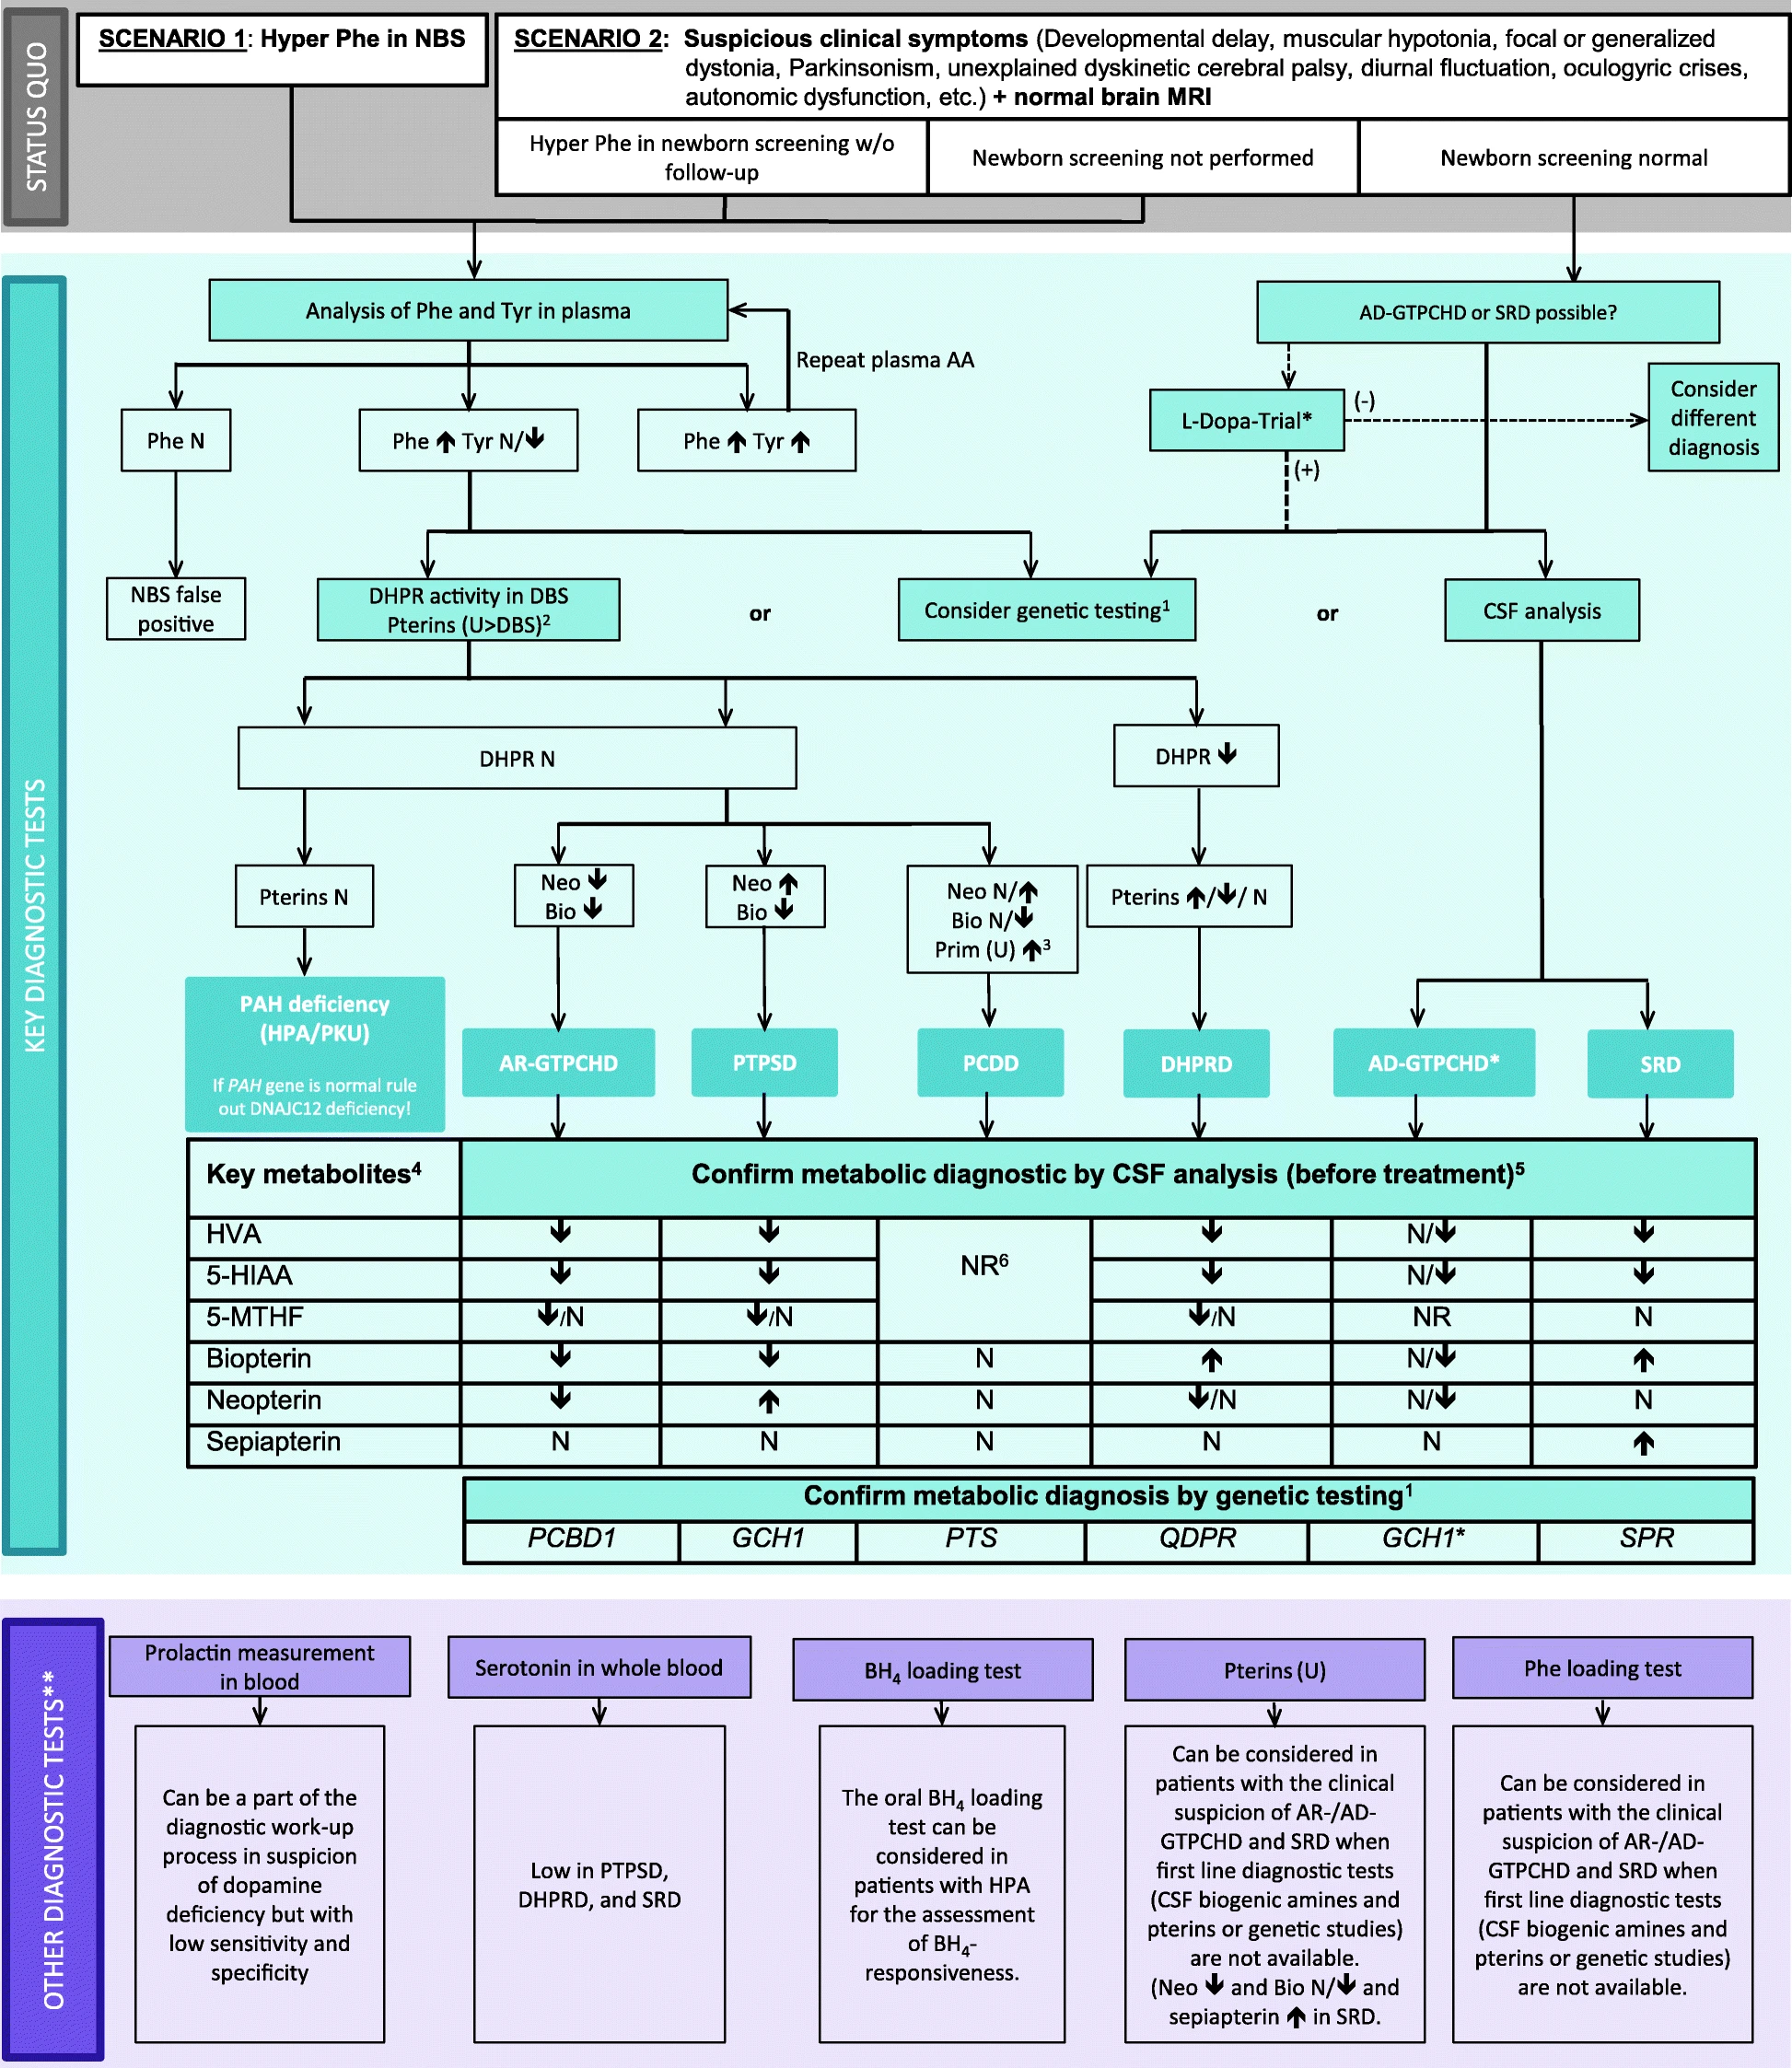
Clinical diagnostic flowchart illustrating decision paths, test evaluations, and branch terminations in medical differential diagnosis. Flowchart: “Diagnostic flowchart for differential diagnosis of BH4Ds with and without HPA ENGLISH” by Thomas Opladen et al. via Wikimedia Commons, licensed under CC BY 4.0.

Navigation and changelogs
Orientation portals and changelogs represent information spaces that change across site architecture and release timelines.
Structure: Navigation map with lateral cross-links. Semantic purpose: documentation orientation. A documentation hub page linking to Getting started, API reference, and Troubleshooting guides, with lateral cross-links between guides.
-
A documentation site navigation network where an entry hub links to core guides, and topic guides maintain lateral cross-references across related tasks without forcing a rigid tree hierarchy.
-
A validator checks every page reachable from the portal, the absence of orphaned pages, and bidirectional cross-referencing between related resources.
-
Navigation maps evaluate whether users can reach information resources, not procedural execution. A site can be fully connected while the user navigation menu remains confusing, bloated, or hard to scan.
Physical analogy: Hyperlinked Wikipedia knowledge globe
Handheld Wikipedia puzzle globe sculpture representing a hyperlinked knowledge space and navigation network. Photo: “Wikipedia mini globe handheld” by Lane Hartwell on behalf of the Wikimedia Foundation, licensed under CC BY-SA 3.0.

Structure: Chronological release sequence with component-impact links. Semantic purpose: change records. A chronological timeline of releases v1.1, v1.2, and v2.0 connected vertically, with horizontal arrows to affected components: Markdown parser, Rule checker, and CI runner CLI.
-
A release evolution model that distinguishes a chronological sequence of software versions from horizontal impact links connecting each release to affected system components.
-
A validator checks strict chronological order along the release sequence, validity of version references, and verification that all impacted components resolve to recognized entries in an architectural catalog.
-
The model explicitly separates chronological release history from component impact. However, structural validation can only check declared relationships; it cannot detect breaking changes or affected components that the author omitted from the changelog prose.
Media analogy: Video game timeline
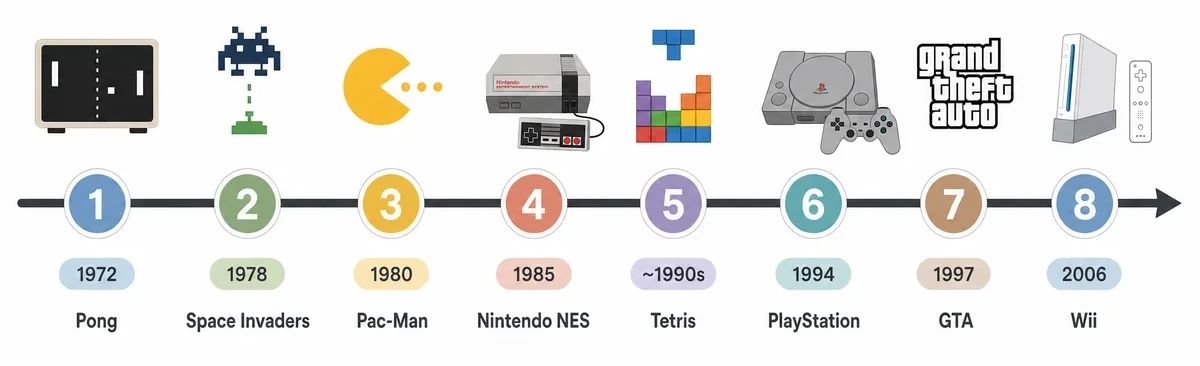
Chronological milestone timeline illustrating sequential releases in the evolution of video games. Graphic: “History of Video Games Timeline” by Kuraplan, licensed under CC BY-NC 4.0.
The validation contract: executing the pipeline
If different document purposes require different structural properties, how would an automated engine decide which rules to apply?
One approach is to define an explicit document type contract for each documentation category. Rather than applying uniform, blanket rules across an entire repository, these contracts tailor validation to the specific structural requirements of the user’s task:
- For procedures, the contract verifies that an action sequence has a single entry point, avoids disconnected steps, and reaches a valid terminal goal.
- For troubleshooting guides, the contract ensures that every diagnostic check branches on both failure and success, that retry loops contain valid exit criteria, and that all paths lead to remediation or escalation.
- For reference topics, the contract prioritizes schema conformity, identifier resolution, and mandatory attributes over step-by-step flow.
A multilayer validation pipeline
We could implement a pipeline using parsing, language-model extraction, and structural checks:
A five-stage architecture connecting Markdown parsing, AI document classification, relationship extraction, deterministic structural checks, and CI enforcement.
The hypothetical pipeline has five phases:
- Parse Markdown: Extract document structure and source locations deterministically.
- Classify purpose: Use AI to identify the intended user purpose, cite supporting evidence, and flag ambiguity.
- Extract relationships: Identify entities, actions, conditions, and relationships, linking each inferred relationship to its source passage.
- Check structural rules: Use deterministic code to check the extracted structure against the rules for its document type, without claiming to verify semantic accuracy.
- Decide pipeline result: Combine validation results and confidence scores to report ok, nok, or dunno. Route uncertain cases to human review rather than treating uncertainty as a documentation defect.
Interpret validation outcomes: three distinct states
With Markdown linters, the situation is simple: a file either passes or fails the test. When you factor in a dose of probability, however, you can no longer rely on a clear-cut go or no go answer.
Possible outcomes are then no longer true or false, but ok, nok, or dunno.
The transition from raw Markdown to a reported outcome follows three distinct operational steps:
- Inference and extraction: The AI model infers the document’s user purpose and extracts a candidate structure of relationships, assigning confidence scores and binding every inferred relationship to specific source passages as evidentiary links.
- Deterministic evaluation: Conventional deterministic code evaluates the candidate structure against the explicit structural rules defined in its document type contract.
- Outcome decision: The system synthesizes the deterministic structural checks with extraction confidence assessments to determine the appropriate status under configured CI policies.
Table 2 compares what the validator establishes for each outcome, illustrates them with examples from our earlier models, and suggests actionable CI responses:
| Result | What the validator established | Suggested CI or reviewer action |
|---|---|---|
| ok [PASS] | The extracted structure has sufficient evidentiary support and satisfies all structural rules defined by its document type contract. This confirms structural validity, not that the structure accurately represents the prose or that the documentation is factually accurate, safe, complete, or linguistically clear. | exit 0: Pass the build. Teams can begin with advisory reporting and enable stricter enforcement as confidence in the validation process grows. |
| nok [FAIL] | Automated structural checks confirm at least one structural rule violation in the extracted structure, such as an unreachable resolution step or a circular prerequisite dependency. This indicates a structural defect in the candidate structure, not necessarily in the prose itself. | exit 1: Block the build or flag the pull request. Report affected document elements, Markdown source lines, and violated rules so authors can investigate and remediate the issue. |
| dunno [REVIEW] | The pipeline cannot establish a reliable result because purpose classification is ambiguous, prose evidence is insufficient, or extraction confidence falls below the configured threshold. This represents uncertainty in AI interpretation, not a confirmed authoring defect. | warn: Notify authors and route the case to human review or a triage queue. Keep inconclusive cases distinct from confirmed violations, regardless of the configured CI enforcement level. |
What structural validation can and cannot prove
This separation represents the central conceptual boundary of the entire thought experiment.
Suppose an AI model extracts the structure of a troubleshooting guide and a deterministic checker confirms:
Every action in the extracted structure leads to a next check, an intentional retry, or a terminal state.
We can verify this statement deterministically with absolute certainty. However, that verification does not prove a fundamentally different claim:
The extracted structure accurately represents the troubleshooting procedure described in the Markdown prose.
The first claim concerns a checkable property of an extracted data structure. The second concerns whether a probabilistic interpretation of natural language is correct.
A structural check cannot ensure the latter is true by evaluating the former.