When does DITA XML content reuse justify its system complexity overhead? Implementing DITA XML reduces authoring volume by referencing single-source facts across multiple manuals. It also introduces XML IDE dependencies, component management overhead, and XSLT stylesheet customization costs.
Enters content reuse economics. Structured authoring pays off when documentation spans multiple languages and product variants; it adds unnecessary complexity for standalone documents.
Single-sourcing productivity mechanisms
DITA XML content references (conref) eliminate text duplication across manuals. Updating a product parameter or warning string in a central source file automatically updates every published output.
Centralizing references in dedicated topic libraries maintains clean content architecture. Authors locate and update single-source facts without hunting across scattered document files.
Architectural overhead
Structured authoring shifts formatting overhead from visual page layout to toolchain management. The bill isn’t the XML markup itself: it’s everything the markup pulls in behind it:
-
XML markup syntax
Requires dedicated XML IDE editors.
-
Multi-block dependency tracking
Requires a Component Content Management System (CCMS).
-
Output layout styling
Requires XSLT and CSS stylesheet pipelines.
-
Process and ownership
Requires systematic process discipline and dedicated technical ownership.
Total system cost
Phrase-level reuse pitfalls
Granular phrase-level reuse breaks multilingual translation. Assembling sentences from individual word references (“Click the”, “blue”, “button”) forces English word order onto French output, yielding ungrammatical translations like “Cliquez sur la bleue flèche”.
Effective reuse models target complete self-contained units: whole paragraphs, steps, or untranslated product names.
Conditional processing (ditaval) filters target content at build time, generating beginner guides, reference sheets, and confidential internal manuals from one unified source repository.
Scope and applicability boundaries
DITA XML delivers maximum value under specific conditions:
- High content reuse: Identical modules appear across multiple product manuals.
- Multilingual translation: Reusing translated blocks reduces localization costs.
- Strict compliance requirements: Standardized structure enforces regulatory consistency.
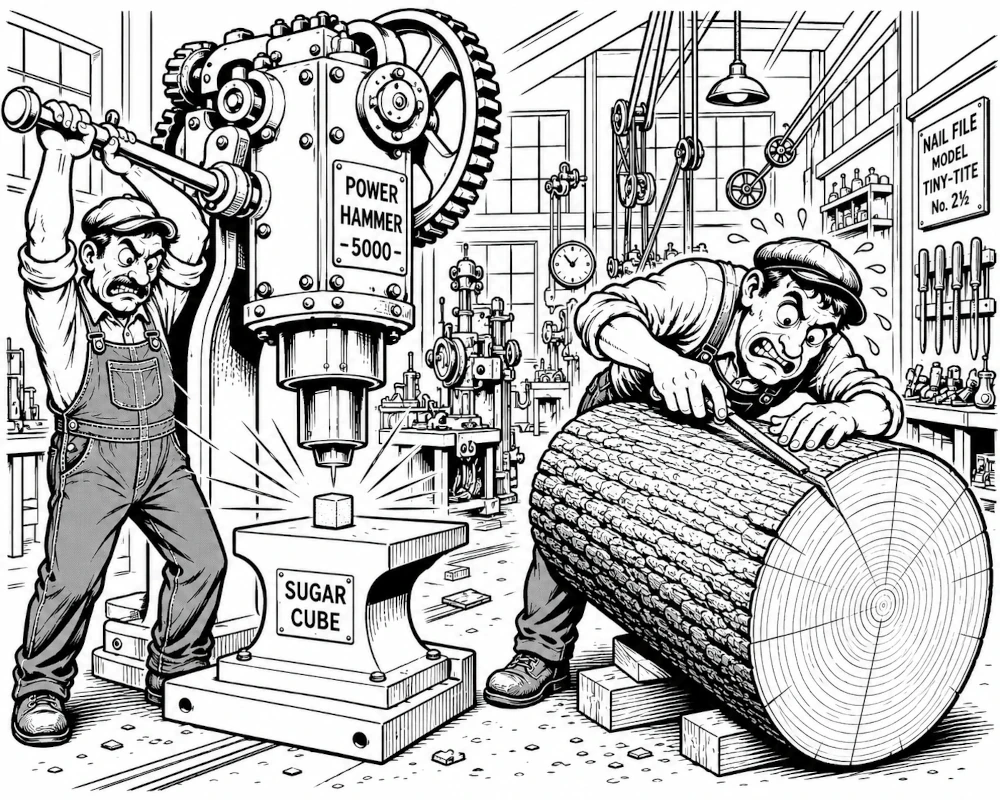
When the complexity doesn’t pay off: For single-language manuals without content reuse requirements, flat Markdown files provide superior agility.
The next step is auditing content reuse metrics across your portfolio to evaluate whether DITA XML adoption justifies toolchain maintenance costs.
Related reading
- A document architecture that’s too complex?: the complexity DITA introduces, and what absorbs it.
- Case study: NuFirewall documentation: conref reuse and conditional text in a real product manual.
- Structured and unstructured formats: where DITA sits on the format spectrum.