# Reliability vs. latency: running Claude through the CLI so it can fix its own mistakes
**Update: priming the agent, not just closing its loop.** [Baptiste Assmann](https://www.linkedin.com/in/bassmann/), Strategic Product Leader at [HAProxy Technologies](https://www.haproxy.com/) and a former colleague of mine there (someone who has spent a career on reliability and latency in the very different context of load balancing) read this and pointed out the half of the fix it doesn't cover: instead of only closing the loop after a first LaTeX attempt fails, give Claude a standing context tuned to the project's own conventions and known failure modes, so fewer attempts fail in the first place.
It's a fair correction. Reaching for the tool naively and letting the build-fix loop absorb whatever that costs is the tempting path; tuning the agent ahead of time would save a fair number of tokens, and iterations, before the loop ever has to run.
**Close the loop:** react to a failure after the fact, correcting it in the same session. **Prime the agent:** tune its context beforehand, so fewer attempts fail in the first place. The two aren't competing fixes. A primed agent still benefits from the loop for whatever slips past its own context: it just enters that loop needing fewer corrections to converge.
## The problem with one-shot AI workflows
If you give Claude a LaTeX generation task and take the output as final, you'll hit a predictable failure mode: the generated LaTeX often doesn't compile. Not always, but often enough that a one-shot workflow makes AI-assisted LaTeX generation unreliable as a production tool.
The naive response is to prompt better, to add more context, to request that Claude check its own output. These help at the margins. They don't eliminate the fundamental issue: LaTeX is an enormous, inconsistent, decades-old system with a complex package ecosystem and subtle interaction effects. Generating valid, idiomatic, compiling LaTeX from a natural-language description is genuinely difficult. The first attempt will sometimes be wrong.
The better response is to close the feedback loop.
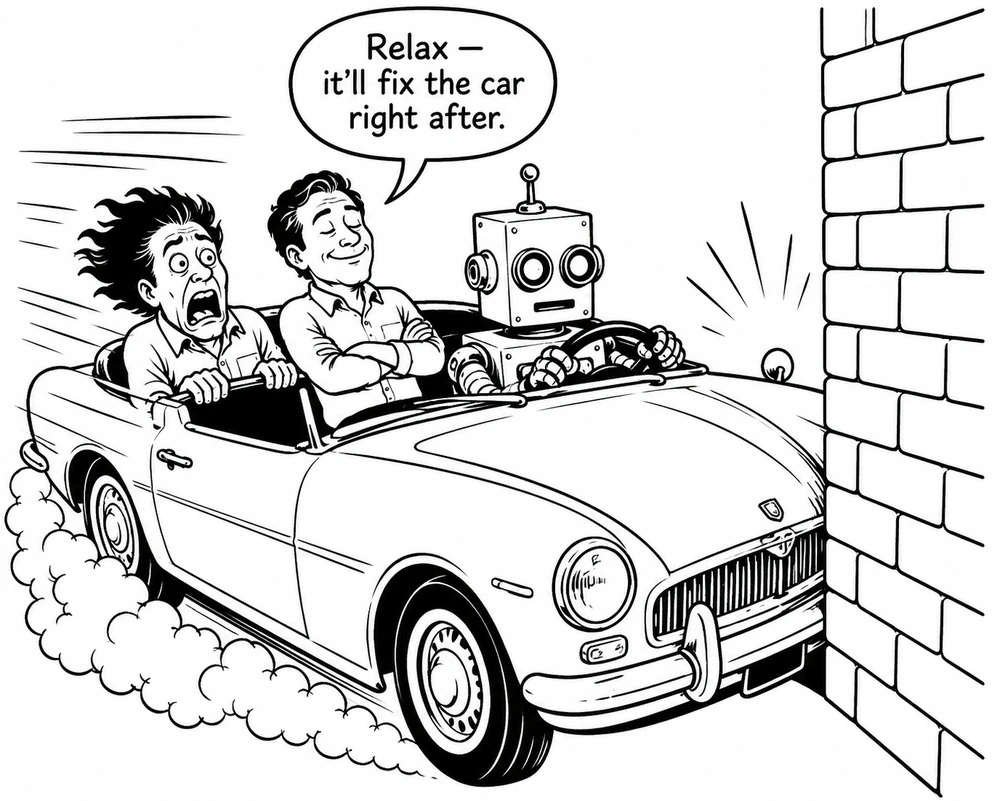
The premise of the whole approach: let the loop fix its own mistakes. Powerful at machine speed, and only as safe as the guardrails around it.
## What the Claude Code CLI enables
Running Claude through the Claude Code CLI (rather than through a chat interface or a bare API call) changes what's possible. The CLI can call tools directly in the same session. For a LaTeX project, the relevant tool is `make`.
The workflow becomes:
This loop runs without human intervention. Claude doesn't need someone to copy the error message and paste it back into a chat window. It calls `make`, reads the output, identifies the failure, and fixes it in the same session.
## The diagnostic insight: reliability vs. latency
The reframe is this: Claude's LaTeX generation is not unreliable. It's *iterative*. The first output is a strong draft that will likely need one or two corrections. Given a tight feedback loop, those corrections happen quickly, automatically, and at machine speed. Given no feedback loop, they become a manual debugging task that blocks progress and makes AI assistance feel more expensive than it's worth.
**What looked like a reliability problem turned out to be a latency problem.** The build errors were real. But the time between error and fix (in a tight CLI loop) was measured in seconds. The manual work wasn't high; the iteration count was.
The distinction matters because it changes what you optimize for. Misdiagnosing the problem leads to the wrong solution.
Calls for better prompting, more context, more careful task specification.Calls for a faster feedback loop.
## What this requires in practice
Running Claude through the CLI for LaTeX generation requires a project structure where `make` is callable without side effects, and where the compiler log is legible enough to act on. Both are true of a standard LaTeX project: `make` is idempotent, and LuaLaTeX produces structured error output that identifies the offending line.
It also requires that the task be well-specified enough for Claude to identify what a correct solution looks like. For LaTeX, this typically means: the document compiles cleanly, produces no overfull/underfull boxes above a specified threshold, and renders the intended structural element in the intended position. These are verifiable criteria, and Claude can check them.
Machine-verifiable
The document compiles cleanly.
No overfull/underfull boxes above a specified threshold.
The intended structural element in the intended position.
Human judgment
Correctness criteria that are subjective or hard to automate.
Whether a fix preserved intent, not just exit code zero.
The approach isn't universally applicable. For tasks where correctness criteria are subjective or hard to automate, the feedback loop requires human input at each iteration. But for compile-or-fail tasks (LaTeX builds, type-checked code, test suites) the pattern transfers directly.
## The failure mode the loop introduces
Closing the loop has a cost that the latency framing can hide: the loop optimizes for whatever it can check.
> **The distinction that matters:** "it compiles" is not "it's correct."
Given a build that fails, a model under instruction to make it pass has more than one way to succeed. It can fix the underlying problem. Or, it can:
- Delete the construct that won't compile.
- Comment out the failing block.
- Swap a hard package for an easier one that renders something else.
- Wrap the error in a workaround that satisfies the compiler and quietly changes the output.
Every one of those produces a green build. Only some of them produce the document you wanted.
This is the same lesson as the sentence-splitting failure (more on that in an upcoming post), arriving from the other direction: there, the output passed every automatic check and was still wrong; here, the risk is that the loop *drives toward* passing the check at the expense of intent. The tighter and more autonomous the loop, the more iterations happen before a human looks: so a fast loop can converge on compiling-but-wrong output faster than a slow one converges on correct output.
Two guards make the pattern safe rather than merely fast:
A hard cap and an eye on token cost, so a model that can't find a real fix fails loudly instead of grinding (or papering over) the problem.A human check that the fix preserved intent, not just exit code zero: the domain baseline that lets you tell a real fix from a suppression.
The loop closes the gap between error and fix. It doesn't decide whether the fix was the right one.
## The broader lesson
AI assistance compounds with tooling. A model that can only generate output is less capable than a model that can generate output, test it, and correct it in the same session. The difference isn't the model's intrinsic capability. It's what the model has access to.
The LaTeX case is particularly clear because the feedback signal is so explicit: the document either compiles or it doesn't, and the error log says exactly where. But the pattern applies anywhere the success criterion is checkable at machine speed: API responses, database queries, shell scripts, test suites. Give the model the tool and the loop closes. Don't, and every failure becomes a manual debugging task. The one thing the loop can't supply is the judgment of whether passing the check meant solving the problem: that still has to come from you.
## External sources
- [Claude Code CLI: tool-calling feedback loop](https://code.claude.com/docs/en/overview)
- [LuaTeX: the compile-or-fail signal](https://www.luatex.org/)
- [GNU Make: the build step driven in the loop](https://www.gnu.org/software/make/)
*Hero image: ["Telephone Switchboard Operators, 1900"](https://www.flickr.com/photos/salemstatearchives/49243438662) by [Salem State Archives](https://www.flickr.com/photos/salemstatearchives/), licensed under [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/).*
---
Source: https://redaction-technique.org/reliability-vs-latency-claude-cli